Token Savings
This card lives in Policy Engine > LLM Gateway at web.quilr.ai/policy. Edits join the shared draft and take effect once you review and publish a revision.
Rewrite request content into fewer tokens before it reaches the provider. Responses come back untouched.
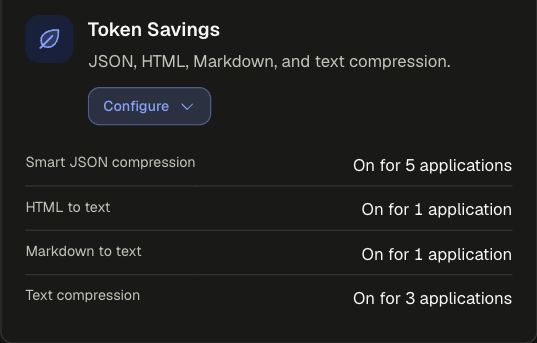
Sections
Each strategy is its own section with a Turn on button. All four apply on chat, responses and vertex.
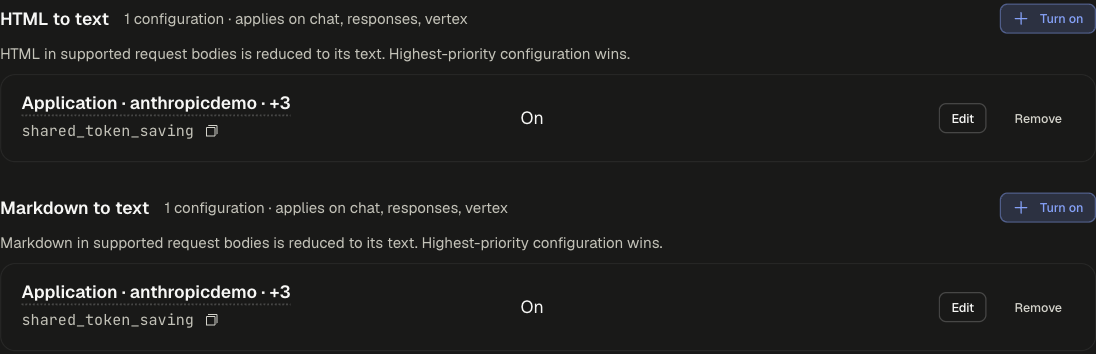
With no configuration, request bodies are sent to the provider as received.
Configuration settings
Any Turn on button opens one New Token Savings configuration dialog with all four controls, preset to the one you clicked.
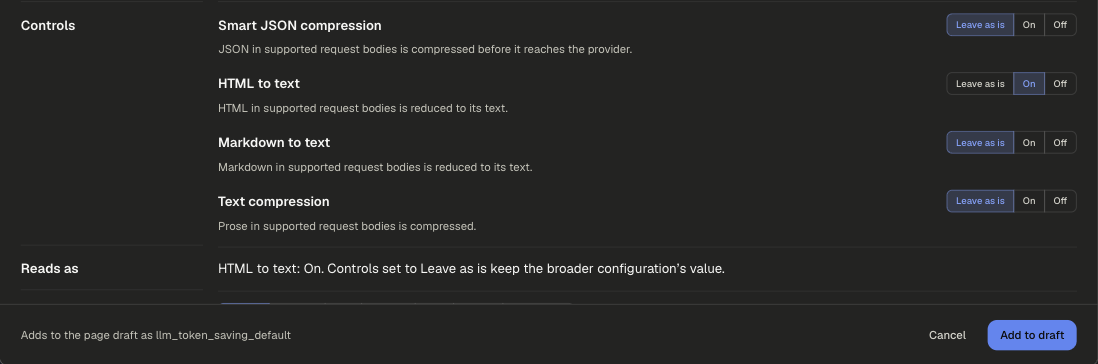
Example
runs on requestpriority 500
A pipeline that sends scraped pages and API payloads turns on the three structural strategies and leaves prose untouched.
Scoping and precedence
- Highest-priority configuration wins per strategy. New configurations start at 500.
- One configuration can cover several apps; it shows as a
shared_*row on each section.
Legacy app setting
Token Saving in the app's settings. For how the strategies work, see Token Saving.